Explore Teos Technology services, products, insights, and ways to connect with our team.
One of my favorite design principles, when it comes to development, is Don't Repeat Yourself (DRY). This principle is foundational in software development and is crucial for maintaining clean, efficient, and manageable code. At its core, the DRY principle emphasizes the importance of reducing repetition within your codebase and processes. The essence of this principle is quite intuitive; many developers are likely employing it without even realizing its significance. The name itself succinctly encapsulates the idea: simply avoid repeating yourself. This concept is not only applicable to the code you write but also extends to the processes you implement in your development workflow.
When you find yourself contemplating the act of copying and pasting code, it's essential to pause
and reflect on what strategies you can employ to avoid unnecessary duplication. Code duplication can lead to a host of issues, including increased maintenance costs, higher chances of bugs, and a more challenging debugging process. Instead of duplicating code, consider creating reusable functions or modules that can be called multiple times throughout your application. This may require a bit of extra care and thought upfront, as you will need to design your code with modularity in mind. However, the long-term benefits of adhering to the DRY principle are substantial. By investing the time to structure your code properly, you will ultimately reduce your maintenance overhead and streamline your development efforts, leading to a more robust and scalable application.
Moreover, think about the manual tasks you perform regularly, whether it's related to product releases, customer engagement, or any other repetitive activity. If you find yourself doing the same task repeatedly, it's a clear indicator that you should consider automating that process. Automation not only saves time but also minimizes the risk of human error, which can be particularly detrimental in critical operations. Implementing automation tools and scripts can free up your time to focus on more strategic aspects of your projects, allowing you to enhance productivity and efficiency. Whatever you choose to do, always keep the DRY principle in mind. By striving to keep your work free from unnecessary repetition, you will foster a more effective and organized approach to development, ultimately leading to better outcomes for both yourself and your team.

When an engineer makes a change to source code or tests, there are multiple steps before that change finally makes it into production. In the most basic form, these steps can merely consist of a developer compiling code on their development machine and copying the output to the production environment. Don't do this. Just don't.
This introduces innumerable opportunities for human error. In order to truly provide reliable deliveries, this process should be automated from end to end. To take it a step further, multiple stages of testing should be incorporated, along the way, to ensure the quality of the release.
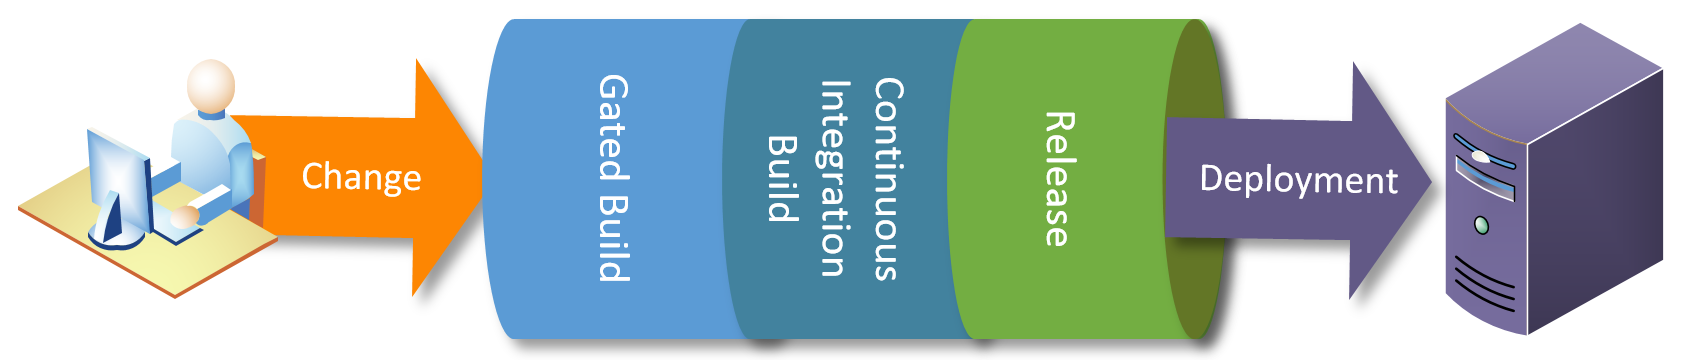
Figure 1: Delivery Pipeline
To begin eliminating human error, some automated workflow needs to be put in place. This consists of a gated build, a continuous integration build, and one or more release definitions. Each build provides another layer of confidence in the quality of the delivery.
It all starts when a software engineer or quality engineer makes a change to source or test code. In order to ensure that the change passes basic inspection, we set up a gated build. The gated build is triggered automatically when the developer attempts to check in a change. It builds the code and executes the unit tests. Only if the code compiles and all unit tests pass, will the change actually be committed to source control.
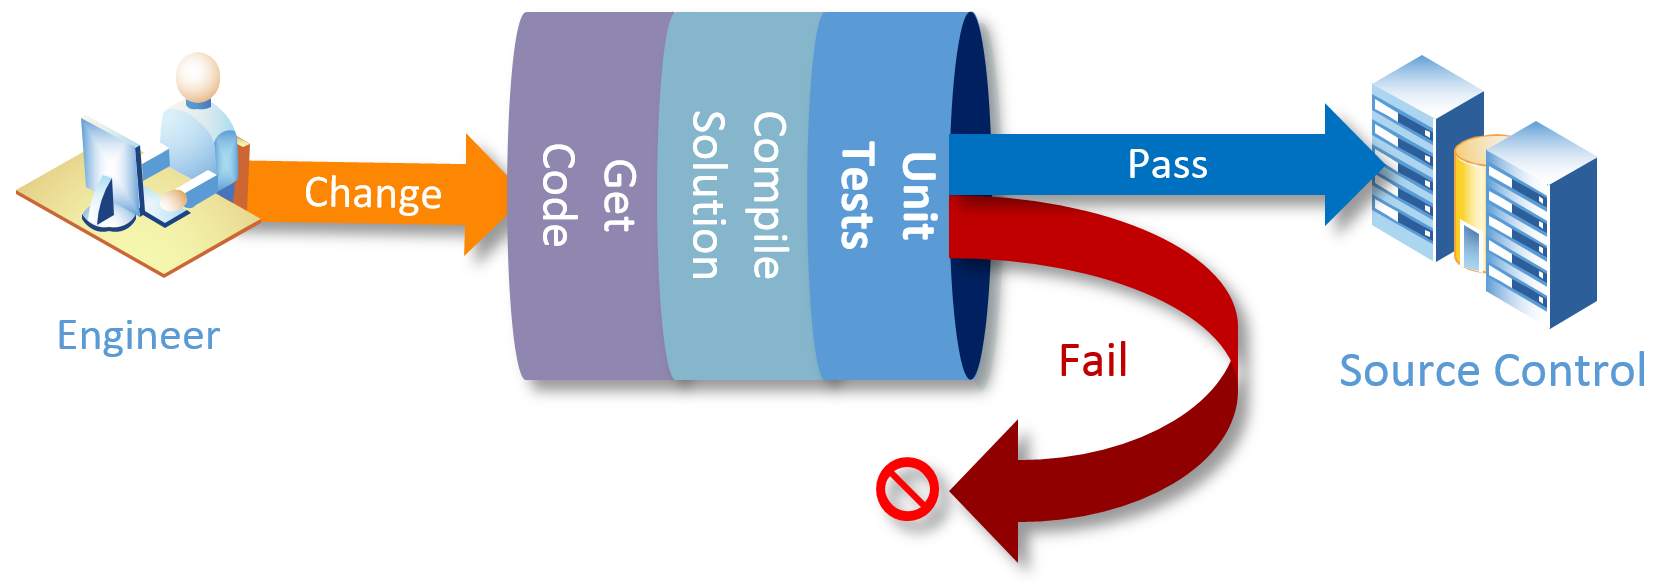
Figure 2: Gated Build
This ensures the health of the code-base in two ways. First, the change actually compiles, thereby preventing blockers for other developers. It is very costly for development to halt, because somebody checked in something that doesn't compile. Second the unit tests ensure that each individual part of the code works as designed. This is the first layer of protection from costly regression errors.
Once the change hits source control, another process is set into motion. The change is retrieved from source control and built, similar to the gated build. This time, however, instead of running unit tests, the build executes functional, integration, and system tests.
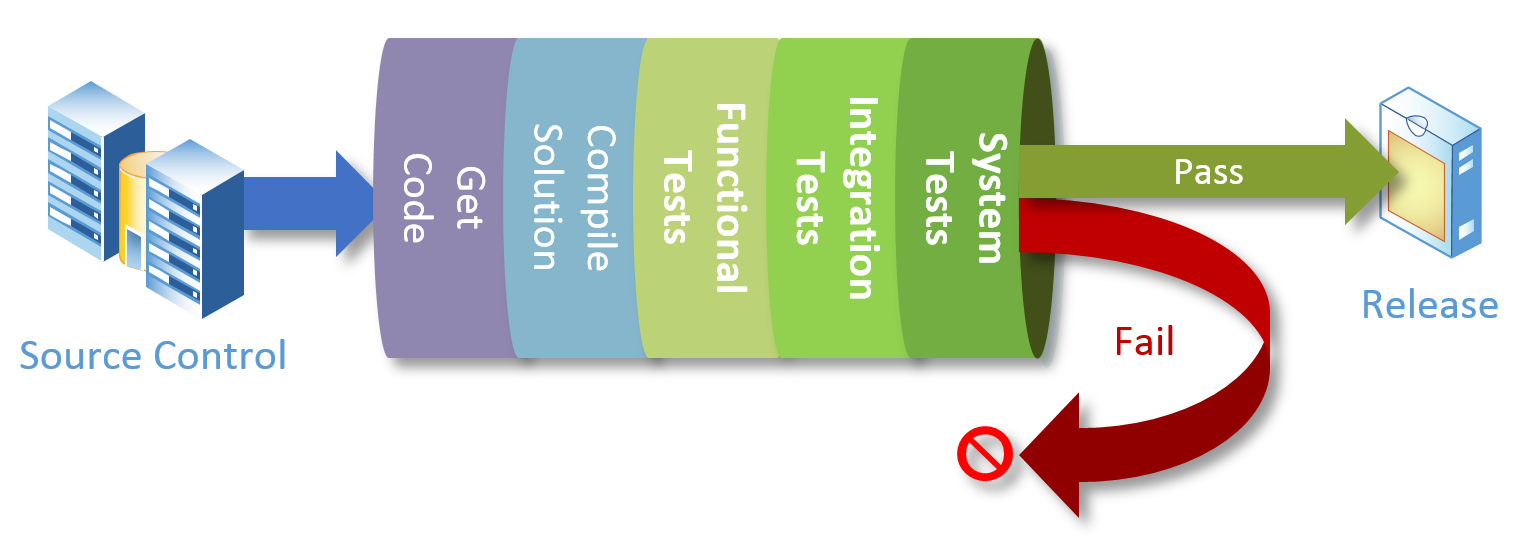
Figure 3: Continuous Integration Build
Each type of testing provides an additional level of confidence in the final product. Functional testing verifies that the individual components behaves according to the requirements. Integration testing ensures that the components work together, and finally, system testing validates the entire system as a whole.
This type of build is known as a continuous integration build, because every change is automatically integrated into the system. Then it is tested against the complete system.
If any test fails along the way, then the entire build fails. It's only if all tests pass that the build artifacts get turned into a release. The entire process is depicted in the following flowchart.
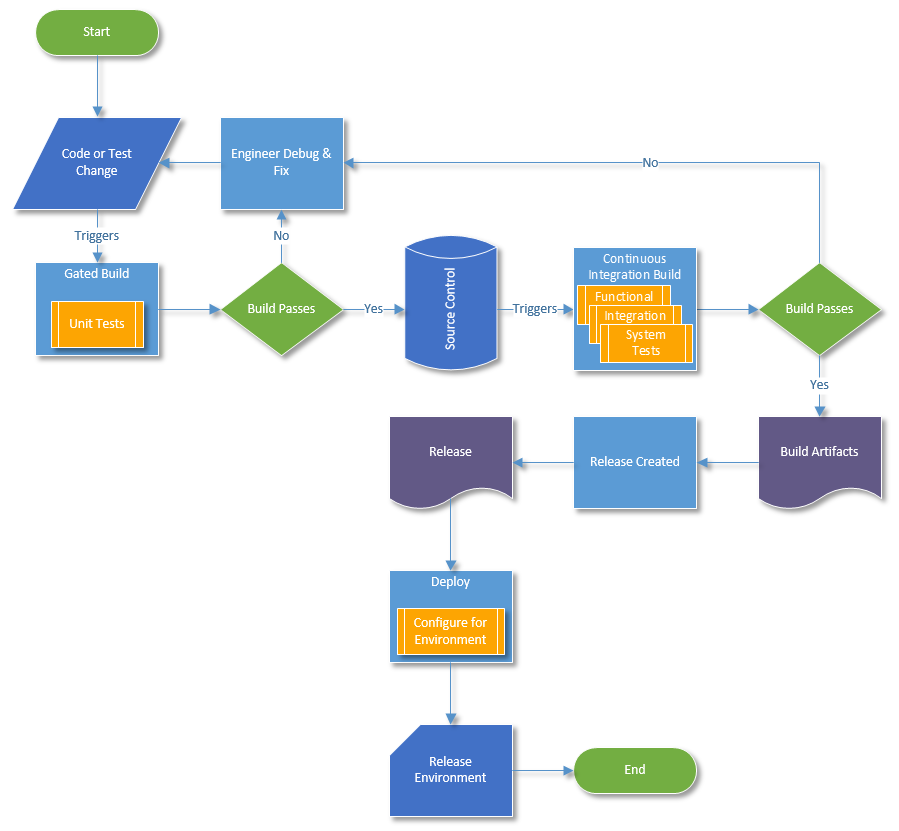
Figure 4: Delivery Workflow
Each step along the way can be automated. For safety and accountability, it's a good idea to add some human control along the way. This is provided at two stops in the chain. The first is creating the release from the build artifacts. Just because you check something in doesn't mean you want to turn it into a release. So this part is left up to a human.
Second, after creating a release, it is up to the humans to decide what to do with it. In an ideal situation, there should be at least three release environments: quality assurance (QA), pre-production, and production. Once a release has been made, it can be deployed to any of these environments.
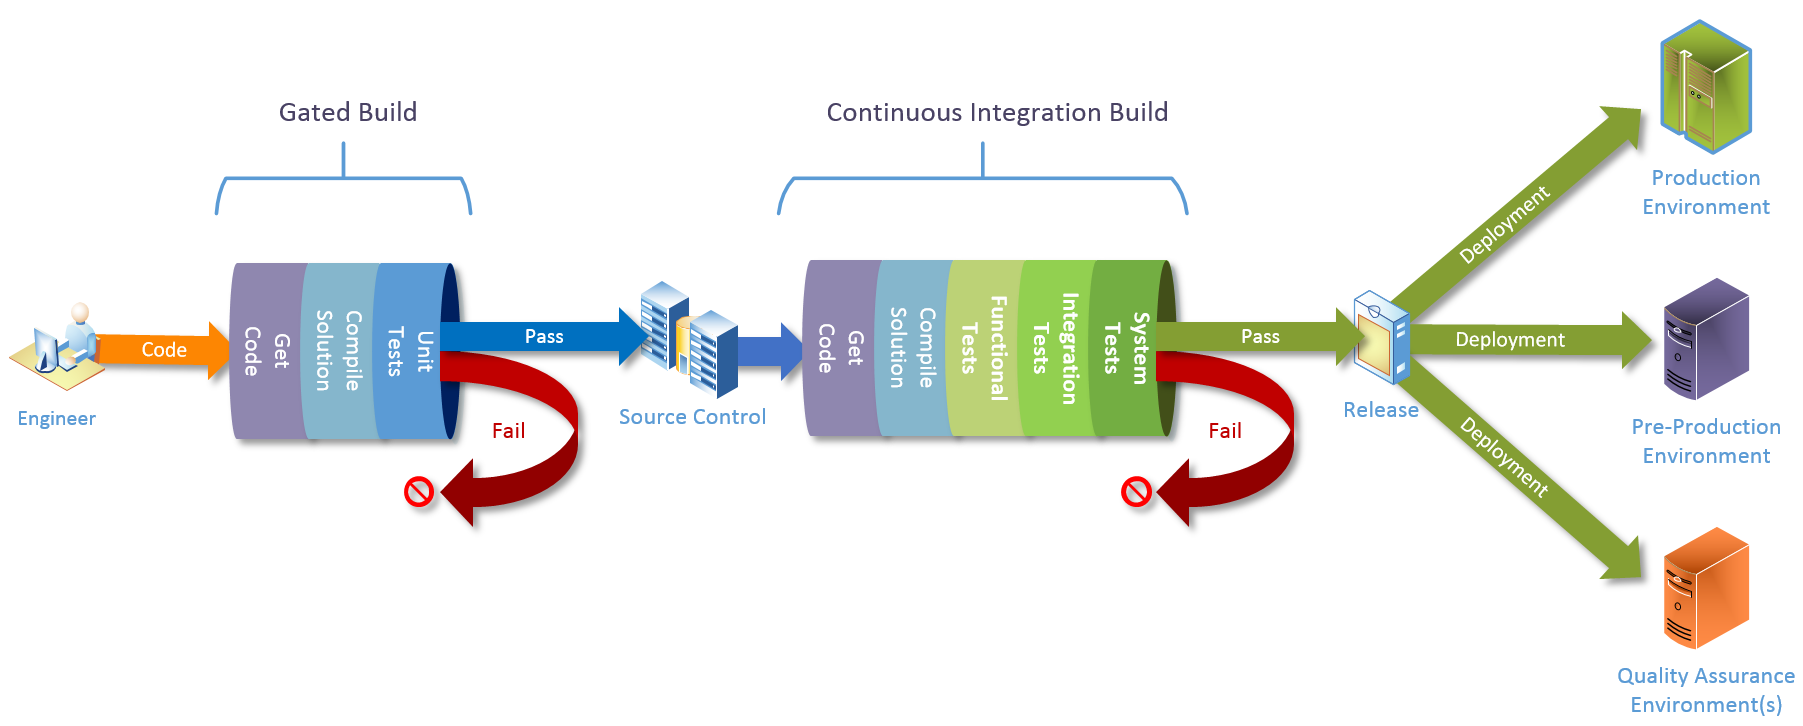
Figure 5: End-to-End Delivery Pipeline
The release would first be deployed to a QA environment, where it would be tested throughout development. When the change is ready to be hardened for an upcoming delivery, the same release can then be deployed to pre-production. Once the team and client are confident in the final quality of the release, it can be deployed to production.
Automating the delivery pipeline takes the guesswork out of providing quality releases. It frees the engineers to focus their time and energy where it matters, rather than on the overhead of integrating changes and running tests manually. If you want to take your process to the next level, automating your delivery pipeline is an investment that will pay for itself.
Do you have your own stories or ideas about automating the delivery pipeline? I'd love to hear from you in the comments!